
Table Import
Table Import writes file data into database tables. DBX parses and previews the source first, then asks you to review parsing options, the target, column mappings, and execution settings before any rows are written.
MongoDB collections do not use this relational workflow. Import CSV/JSON documents from the collection document page instead; see MongoDB Workspace.
Target Modes
| Target mode | Behavior | Typical use |
|---|---|---|
| Existing table | Loads target columns and maps source fields; supports append or truncate-then-import | Backfills, test data restoration, and sample data replacement |
| Create new table | Infers column types from preview data and lets you edit the table name, column names, and types | Fast file-to-table workflows, spreadsheet migration, and multi-file imports |
Create-table mode accepts multiple files at once. Excel workbooks are expanded into separate tasks per worksheet. DBX suggests a table name for each file or sheet and requires the final names to be unique. Tasks run sequentially and keep independent previews, mappings, and type settings.
Supported Files
| Format | Details |
|---|---|
| CSV | Comma-delimited by default, with configurable header row, row range, and encoding |
| TSV | Tab-delimited text |
| Delimited text | Files such as .txt with a custom delimiter |
| JSON | A single object, object rows, or array rows; the shape can be selected explicitly |
| Excel | .xlsx, .xlsm, and .xls, with worksheet selection |
| SQL | .sql scripts containing literal INSERT INTO ... VALUES statements for one table |
| Parquet | .parquet files, available when the target connection is DuckDB |
| Navicat backup | .nb3 archives, available from the database-level entry of MySQL and PostgreSQL connections; see Navicat Backups |
SQL import accepts only literal INSERT INTO ... VALUES rows. Expressions, REPLACE, INSERT IGNORE, INSERT ... SELECT, and other constructs that cannot be rewritten losslessly are rejected so data and statement semantics are preserved. When a file cannot be previewed because it is not a single-table INSERT dump — a full-database export, for example, carries CREATE and INSERT statements for many tables — the dialog says so and offers Execute SQL File, which streams the script in chunks and suits large files.
SQL import streams the script in chunks instead of loading it into memory, so there is no file-size limit and memory use stays flat on large dumps. The total row count is only known once the script has been scanned to the end, so progress during import is reported by bytes read and the row count appears when the import finishes. Because rows are written while the script is still being scanned, a statement that fails half-way leaves the rows already written in the target table; the preview step parses the entire script first, so a malformed dump is normally rejected before any data is written. Values written with date functions such as TO_DATE and TO_TIMESTAMP are imported as the text of their first argument, and the target column must be able to parse that format.
Excel import reads .xlsx and .xlsm workbooks incrementally: the preview stops after the rows it needs and the import produces bounded row batches, so large workbooks have no file-size limit either. Legacy .xls workbooks still load the whole file through the Excel reader and are limited to 50 MB.
Desktop reads selected local files directly. Docker/Web uploads browser-selected files to temporary server storage, then releases the prepared source after preview and import finish.
Parquet import uses the selected DuckDB connection's native Parquet reader. The same preview, mapping, new-table, append, and truncate workflow applies, while other database types do not offer Parquet as an import format. Large Parquet sources are read in bounded batches; nested values remain subject to the target column type and DuckDB conversion rules.
Navicat Backups
When Table Import is opened from a database (not from a table) on a MySQL or PostgreSQL connection, the source step also offers Navicat backup. Choose the card, or pick a .nb3 file with Select File, and DBX opens SQL File Execution with the same connection, database, and archive already filled in, so the backup restores straight into the database you started from.
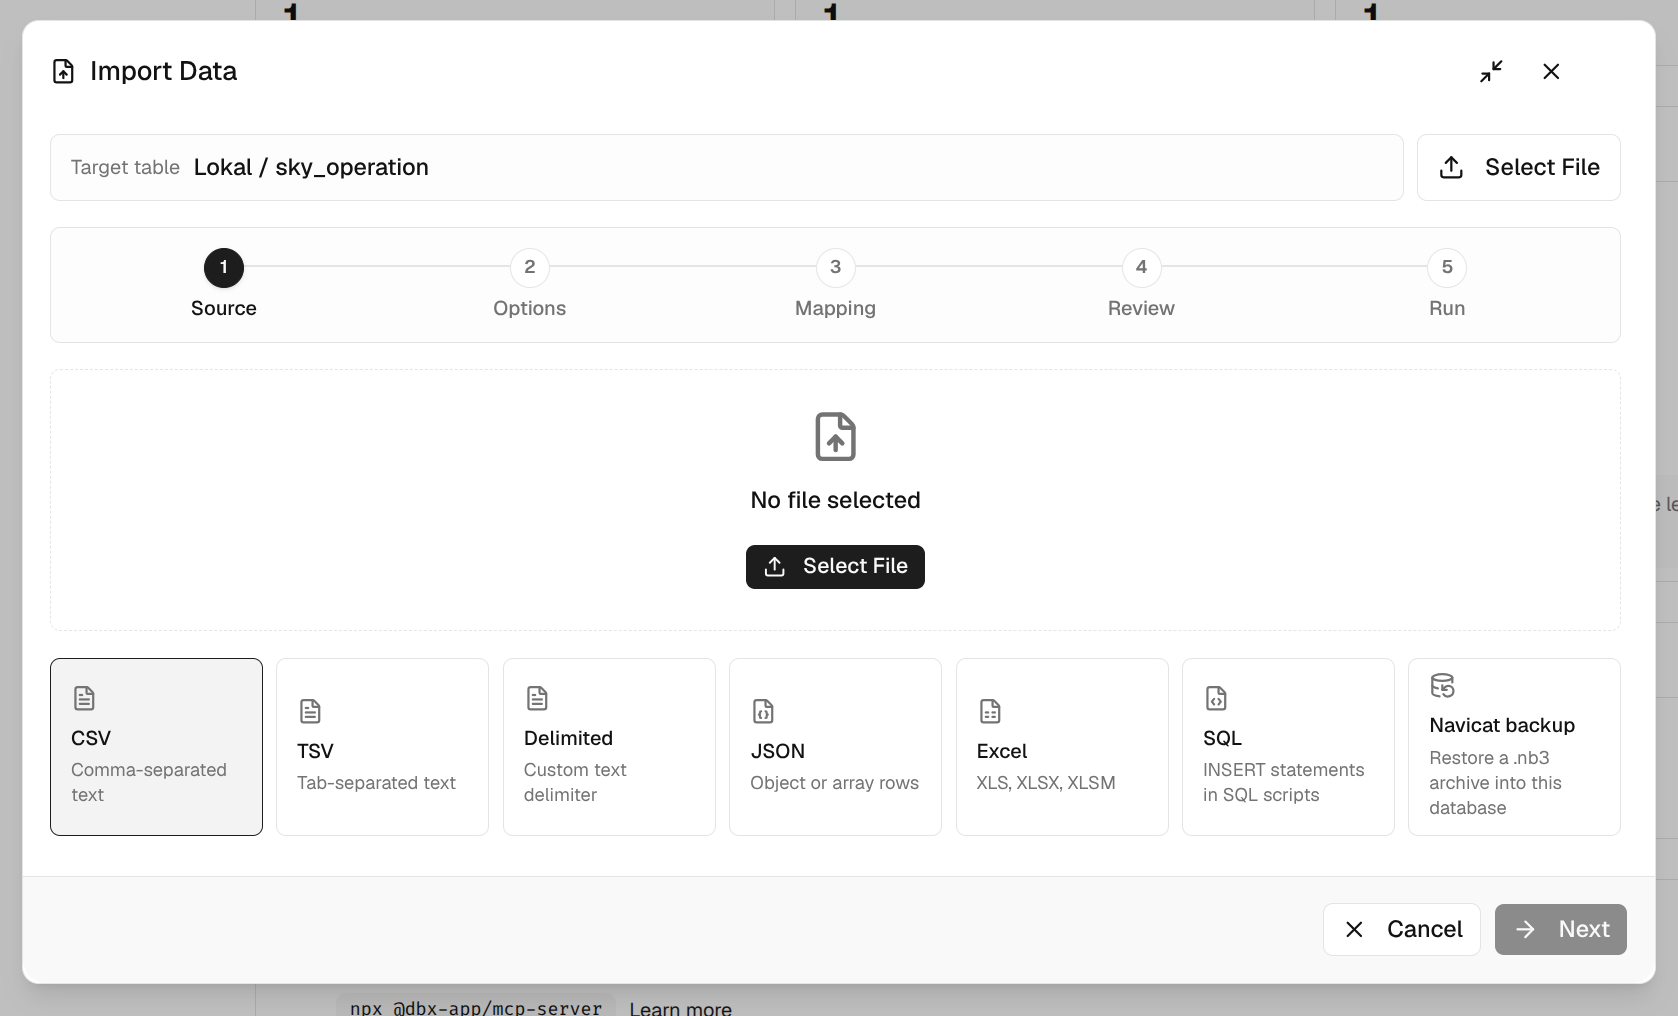
The archive is restored as a whole database script rather than through the column-mapping wizard: it drops and recreates the archived tables, views, and routines, loads their rows, then adds indexes, constraints, and triggers. Restore into an empty or disposable database first, and keep a backup of the target. Encrypted Navicat archives are not supported. The same archives can also be restored from Database Backup with Restore from file.
Import Wizard
Choose Files and Target Mode
Opening the action from a table preselects that table. You can instead create a new table and select one or more files.
Configure Parsing
Review encoding, title row, data range, worksheet, JSON shape, empty-string behavior, and whitespace trimming.
Review Column Mapping
Map source fields to an existing table, or review inferred names and data types for a new table. Use the data preview to verify real values.
Review the Plan
Confirm the connection, database, schema, table name, import mode, mapping count, estimated row count, and batch size.
Run and Inspect Results
The execution view reports reading and writing phases, imported rows, byte progress, elapsed time, errors, and cancellation state.
Parsing Options
Text Encoding
CSV, TSV, delimited text, and SQL scripts support auto detection, UTF-8, GBK, UTF-16 LE, and UTF-16 BE. If detection is wrong, select an encoding manually and recheck the preview.
Row Range
- Title row chooses the row used for field names
- Data start row skips leading notes or blank rows
- Last data row limits the import;
0reads to end of file - Preview rows controls the mapping preview only, not the final import size
Value Handling
- Trim values removes surrounding whitespace from text values
- Empty string as NULL is enabled by default; disable it to preserve empty strings
- JSON shape can be detected automatically or forced to object rows or array rows
- Worksheet selects an Excel sheet; batch create mode creates an independent task for each sheet
Mapping and Table Creation
For existing tables, DBX first matches exact names, then normalized names. Normalization ignores case and differences in spaces, underscores, and hyphens.
- Source columns can be skipped
- A target column cannot be mapped more than once
- At least one column must be mapped
- Required unmapped columns need a default, auto-generated behavior, or nullable definition
For new tables, source columns initially map to same-name targets and DBX suggests database-specific types from preview values. Suggestions are only a starting point; review dates, precision, long text, JSON, binary values, and engine-specific types before execution.
Modes and Batches
| Option | Behavior |
|---|---|
| Append | Keeps existing rows and inserts new ones |
| Truncate then import | Clears the target table on supported paths before writing file data |
| Batch size | Controls rows written per batch; the default is 500 |
New-table and multi-file imports always use append because each target is created by the current task. Truncate-then-import is destructive, and transaction or TRUNCATE semantics differ by database. Do not assume every completed operation will be rolled back after a later failure.
Database Coverage
DBX exposes Table Import through the driver capability manifest. Only connections that implement column discovery, table creation or writing, and required type conversion enable the action. Specialized Redis, MongoDB, search, vector, message queue, and configuration-center workspaces use their own workflows instead of this relational table importer.
Being able to connect does not imply Table Import support. If the action is absent, check the database type, driver mode, and DBX version before treating it as a privilege problem.
Failure and Cancellation
Continue After Failed Rows
By default a failed statement aborts the whole import. Continue after failed rows changes that: a failed multi-row batch is retried row by row, and the import keeps going while every failed row is reported with its target table, source row number, and error. The summary shows "imported N rows, M failed", and the failed-row list (up to the first 1000 entries) can be copied for a follow-up fix. Rows in a failing batch are written one by one, so imports with errors run slower. The option is off by default.
- Parsing failures usually indicate an incorrect encoding, delimiter, title row, JSON shape, or worksheet setting
- Write failures usually come from type mismatches, required columns, key conflicts, privileges, or target schema differences
- Cancellation stops later batches, but already committed batches are not guaranteed to roll back
- Batch create tasks run sequentially; a failed task keeps its error state, while previously completed tables are not automatically removed
Related Features
Database Documentation
Browse a schema as documentation, annotate tables and columns with notes and colour-coded groups, and export DBML for dbdiagram.io or CI drift checks.
SQL File Execution
Preview and execute one or more SQL files in order with per-file statistics, statement progress, and failure reporting.