
Database Support
The new-connection picker provides 100+ database and service profiles. A profile defines defaults, form fields, presentation, and a driver entry point, but being able to connect does not mean every advanced feature is available.
crates/dbx-core/assets/database-drivers.manifest.json are authoritative for current types and capabilities. This page intentionally avoids a brittle exhaustive matrix.Connection Families
SQL and Compatible Protocols
- Core SQL engines such as MySQL, PostgreSQL, SQLite, SQL Server, ClickHouse, Oracle, and Redshift
- MySQL-protocol or syntax profiles such as MariaDB, TiDB, OceanBase, Doris, SelectDB, StarRocks, Manticore Search, GoldenDB, and Dolt
- PostgreSQL-compatible profiles such as openGauss, GaussDB, KingbaseES, HighGo, Vastbase, and CockroachDB
- Vendor databases including DM, KWDB, YashanDB, GBase, Teradata, Vertica, Exasol, Firebird, and SAP HANA
- Agent/JDBC analytics engines such as Snowflake, Trino, PrestoSQL, Hive, Spark, DB2, Informix, Databricks, and BigQuery
- Cloud-managed relational services such as Google Cloud Spanner (Agent/JDBC, GoogleSQL and PostgreSQL dialects)
Protocol compatibility covers only connection and selected dialect behavior. Versions, system catalogs, DDL, privileges, and management APIs differ, so DBX uses separate profiles and capability overrides instead of enabling features by family name alone.
File, Edge, and Hosted Databases
- SQLite, DuckDB, and Microsoft Access
- Cloudflare D1, Turso, and RQLite
- H2 and local databases reached through JDBC URLs
A self-hosted libSQL server (sqld) uses the Turso profile. Enter the server URL as the host, for example http://127.0.0.1:8080, and leave Auth Token empty unless the server checks JWTs (--auth-jwt-key-file). An http:// URL stays plain HTTP while SSL is off; libsql:// URLs and bare host names use HTTPS.
Desktop file paths belong to the local computer. Docker/Web paths belong to the server container or mounted host storage; a path on the browser computer is not mapped automatically.
Specialized Data Models and Services
- Redis, MongoDB, and Apache CouchDB
- Elasticsearch, Easysearch, Meilisearch, and Manticore Search
- Qdrant, Milvus, Weaviate, and ChromaDB
- HBase
- Pulsar, Kafka, RocketMQ, and RabbitMQ
- etcd, ZooKeeper, Nacos, and Consul KV
- InfluxDB, IoTDB, TDengine, and other time-series or IoT profiles
These connections use key-value, document, search, vector, messaging, or configuration-center workspaces. They do not inherit every relational grid or SQL concept. See Specialized Workspaces.
Driver Runtimes
| Runtime | Description | Typical boundary |
|---|---|---|
| Built-in native | Rust driver compiled into DBX | Available immediately after installation |
| Native Agent / sidecar | DBX-managed Go, Rust, or external process | Requires platform files; DuckDB, Oracle, KingbaseES, XuguDB, RabbitMQ, and similar paths may use separate runtimes |
| JDBC Agent | Java Agent plus a vendor JDBC driver | Requires a JRE, Agent, and legally obtained vendor JAR |
| JDBC plugin | Optional generic JDBC extension | Unknown engines run with generic JDBC capabilities |
See Driver Management for installation, upgrades, offline packages, and runtime monitoring, and JDBC Plugin for custom JDBC.
Oracle OCI (thick driver)
Oracle connections default to the thin driver. The connection dialog's driver mode also offers OCI, which runs the separate oracle-oci Agent built against the Oracle Call Interface so the Oracle Client handles the connection. The OCI driver is currently shipped for Windows x64.
- Instant Client directory is a global setting: enter the directory that contains
oci.dllonce, and every OCI connection reuses it. The directory is prepended to the Agent process's loader path. - NLS_LANG is process-scoped for the Oracle Client, so it is configured in two layers: a global default, plus an optional per-connection override. A connection that overrides NLS_LANG gets its own Agent process instead of sharing one, so character sets never leak between connections.
- TNS names, wallets, and sqlnet.ora:
TNS_ADMINsupports a global default plus a per-connection override (fill the directory in the OCI connection form, or leave it empty to follow the global default), so any OCI connection can use tnsnames.ora aliases, ADB wallets, and sqlnet.ora network options (compression, encryption) without switching to the TNS connection form; the TNS connection form also passes its directory to the Agent process. - OCI only affects how the client library is loaded. Grid editing, DDL, transfer, and other features behave the same as on the thin driver.
Capability Levels
The driver manifest uses capability levels from basic connection through controlled operations, with per-engine overrides:
| Level | Meaning |
|---|---|
| Connect | Establish a connection and run profile-supported basic queries |
| Browse | Browse databases, schemas, tables, or specialized objects |
| Understand | Add read-only source, search, and relationship workflows |
| Operate | Add controlled writes such as table data editing |
Individual capabilities then control features such as:
- Schema search and ER diagrams
- Table data and table structure editing
- Table import and data transfer
- SQL file execution
- Field lineage and query explain
- Database creation, user administration, and driver management
Menu availability is therefore more meaningful than a static database name list. When an action is missing, check the DBX version, database profile, runtime mode, and installed components.
Feature Boundaries
SQL Files and Relational Tools
Redis, MongoDB, search, vector, HBase, configuration-center, and message-queue workspaces do not use relational SQL file execution. Some SQL engines support query and browse workflows without structure editing, import, or transfer.
Import and Transfer
Table Import and Data Transfer filter connections by capability. Cross-engine paths also depend on type mapping, keys, identity columns, schemas, and target DDL support.
Backup and Export
- Database Export is a capability-driven logical SQL export
- Database Backup currently schedules consistent MySQL, PostgreSQL, and openGauss backups in Desktop only
- Cloud Sync and configuration export migrate DBX settings, not business database contents
Native Job and Scheduler Management
Oracle and OceanBase Oracle connections expose Native jobs; Dameng retains Agent Jobs. They share the same management page. Use Job type to select Scheduler or traditional Job, with SYSJOB agent jobs available for Dameng. Owner filtering and search run against the database rather than only the loaded page. Scheduler jobs with the same name are selected separately by owner.
Scheduler creation and editing provide definition, argument, and advanced-attribute sections. Arguments distinguish keeping the original, unset, inherited default, SQL NULL, and explicit values; native values that cannot be safely converted remain unchanged. Preview changes, confirm, and inspect the result in the same page. Traditional jobs retain their native numeric IDs and display LOG_USER, PRIV_USER, and SCHEMA_USER separately. When creating a traditional job, SCHEMA_USER sets the execution schema, not the login identity.
When creating a Scheduler job, select a Program, named Schedule, or Chain from the catalog where applicable. Credential and Destination selection is available under advanced attributes. The catalog filters by owner and name, pages results, and shows the actual readable scope. You can enter exact names when the catalog is unavailable. Selecting a Program or named Schedule retains the corresponding inline fields in the draft without writing them; clear the reference to edit those inline fields again.
For a referenced Program, argument counts and defaults come from the Program rather than the job's inline argument count. The argument section shows defaults separately from explicit job values; database-supplied metadata arguments cannot be overridden. An unresolved default is not treated as SQL NULL. Creation and Oracle reference editing retain separate Program and inline argument drafts instead of applying old overrides to the newly selected Program.
Oracle argument values offer plain text or an explicit ANYDATA scalar type. SQL NULL retains the selected type; it is distinct from unset or inherited. Enter NUMBER as complete decimal text. Date and time inputs are separate; timestamps retain up to 9 fractional digits, and local-time-zone timestamps are edited in UTC. INTERVAL uses total months or nanoseconds, RAW uses hexadecimal, and BINARY_FLOAT/BINARY_DOUBLE use complete bit patterns. Program defaults use the same controls in read-only mode. Values that cannot be read losslessly remain read-only. Lightweight jobs do not offer ANYDATA input.
When editing an existing Oracle Scheduler job, use the same editor to change its Program, Schedule, Window, Window group, or Chain, and choose credentials and destinations under advanced attributes. After selecting a Program, review its arguments and choose the final enabled state. The preview includes pausing future scheduling and conditional argument settings or resets. Arguments already at their target are skipped; conflicting external changes stop the operation. The selected enabled state is applied only after the definition and arguments have been verified.
Oracle's Trigger selector offers a date or repeat rule, a named schedule or window, a queue event, or a file arrival event. Queue events have separate owner, queue name, optional AQ agent, and condition inputs. File arrival events reuse the File watcher picker. Inactive time and reference inputs stay in the draft without being written. Destination groups are selected as references, not expanded or modified; an incompatible job type is rejected during preview with the input retained for correction.
Under Oracle's advanced attributes, Execution target selects local execution, a legacy remote host (host[:port]), or a named destination or group. Host text is edited verbatim, not parsed as an object name. Switching modes retains inactive drafts, while the preview includes only the selected mode. Select local execution to clear the previous remote target.
After partial success, inspect the current state and use Correct draft to read and preview again. Restore original definition draft puts the initially read definition back in the editor; it does not roll back the database. Review the current state and confirm a new preview before applying it. Editing does not automatically run the job.
For asynchronous Run or Stop, Accepted describes the management request, not the job's business result. Native execution observation in the same result area shows running/history read states and identifiable instances; use Refresh run result to read again. Newly observed success, failure, or stop records are not automatically attributed to this request, and uncertain association is stated explicitly. The absence of a running row does not prove that the job never ran or that this request stopped it. DBX does not automatically rerun the job on that evidence.
Reference lists require read access to the corresponding system views. OceanBase V4.2.5 uses SYS.DBA_SCHEDULER_PROGRAM, not Oracle's plural name. An account without read access can receive ORA-00942. An unreadable list does not establish that the referenced object is absent; DBX does not grant privileges automatically.
OceanBase V4.2.5's Job and Program argument views are compatibility placeholders that always return no rows, including when arguments exist. DBX reports that argument metadata cannot be read instead of treating it as an empty argument list. Readable definition fields and controls that do not depend on those arguments remain available.
Existing OceanBase V4.2.5 Scheduler jobs have read-only base definitions. Use Advanced attributes to edit the job class, maximum failures, maximum run duration, and execution Zone. Durations use a nonnegative, whole-second DS interval, such as 0 00:02:00 for two minutes. A Zone is a name or RANDOM, not an Oracle numeric instance. Maximum failures is read from the native view after checking the job identity; an unreadable value does not block other editable attributes. Fields that cannot be cleared have no clear action.
Creation accepts a different set of inputs: initial action, dates, repeat expression, and comments remain available, with 0–255 arguments and the STORED_PROCEDURE or PLSQL_BLOCK job types. This version does not offer named Schedule, Credential, or Destination creation inputs. Program references follow its native naming rules.
OceanBase traditional jobs use a nullable Zone name rather than an Oracle numeric instance. Creation requires a matching OceanBase Agent or Generic JDBC runtime; if DBX requests an update, update the runtime and reconnect. An administrator must also enable the database's DBMS_JOB package; DBX does not change the global switch. Creation sets and verifies the selected enabled state and date before the first commit. Enabling or disabling preserves the latest next-run date read during execution.
Oracle and OceanBase traditional jobs use Run in foreground, which waits for the native call to return. On the verified OceanBase 4.2.5.7 configuration, running also clears the broken flag and recalculates the next-run date; review this scheduling effect before confirming the preview. Traditional DBMS_JOB has no native stop operation; ending a session is not a substitute. Oracle Scheduler exposes separate normal and Force stop previews and confirmation. OceanBase does not reuse Oracle's force-stop signature.
Dameng SYSJOB Jobs
This release does not yet implement these DM operations: attaching or detaching Program/named Schedule references when switching an existing Scheduler job to or from an inline definition, argument RESET/default inheritance restoration, job execution-schema migration, and traditional DBMS_JOB creation. DBX does not dispatch native calls whose contracts have not been confirmed. The Oracle reference-editing and traditional-job creation capabilities above do not extend to DM; these DM operations require confirmed native contracts before implementation. Native Oracle and DM8 database acceptance testing remains deferred. Automated tests and UI checks with mocked external boundaries do not establish database acceptance.
Open Agent Jobs from a Dameng connection to manage SYSJOB jobs. Search by name, owner, or description, then select a job to read properties, steps, schedules, current runs, and history separately. An unavailable or denied section is shown explicitly rather than treated as empty.
To create a job:
- Click New Job, enter its name, and choose the final enabled state under Job properties.
- Under Steps, enter SQL or native configuration input. Add multiple steps and configure success/failure actions and next steps. Use Schedules to add one or more schedules.
- Click Preview SQL, review the target and configuration, and confirm. DBX creates the job disabled, completes configuration on one physical session, and verifies readback before applying the selected final enabled state.
Use Edit job for existing jobs. Unchanged properties and children are preserved. A backup, restore, or DTS step's catalog COMMAND may be database-generated SQL; changing its definition requires the original native configuration, not the generated command.
For a partial or unknown result, use Read again, Correct draft, and Check operation result in the original result area. Acknowledged jobs and children retain their native IDs. An uncertain add is not automatically adopted by name or created again. Correct the draft and confirm a fresh preview to apply remaining changes; business jobs are not rerun automatically.
Stop remaining steps only cancels management steps not yet dispatched. Use Stop Current Run to request native job stopping; disabling future scheduling does not stop a current run. A missing job environment has a separate Initialize Job Environment action and is never initialized automatically.
Desktop and Docker/Web
Both runtimes share most Rust core query, metadata, and safety policy, but are not feature-identical. Local SQL folders, system file selection, Deep Links, local CLI Agents, and scheduled database backup are Desktop-only. Web files, drivers, and Agents live in the server data directory.
Default Ports and Connection URLs
Profiles prefill common defaults such as MySQL 3306, PostgreSQL 5432, Redis 6379, MongoDB 27017, SQL Server 1433, Oracle 1521, Elasticsearch 9200, CouchDB 5984, Meilisearch 7700, and RabbitMQ AMQP 5672. These are defaults, not requirements.
Services such as RabbitMQ may expose separate business and management ports. A custom AMQP port must not be used to infer the Management API port. SSH tunnels, HTTP proxies, TLS SNI, and physical dial targets should also be verified independently.
DBX parses many common DSNs and URLs, but parameters vary by version and cloud vendor. After a successful connection test, still verify the actual database, schema, SSL, and privilege scope.
Elasticsearch API Key Authentication
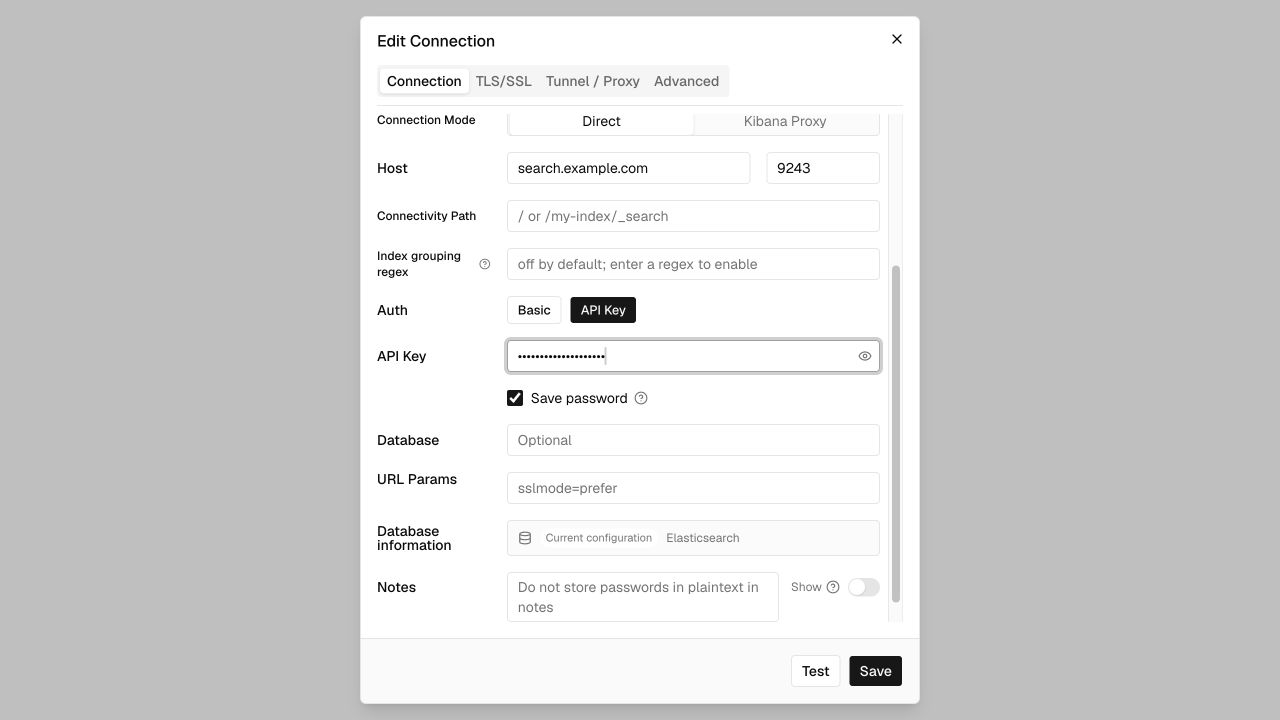
In the connection form, choose Auth → API Key and paste the encoded Elasticsearch API key (Base64(id:api_key)) into the masked API Key field. Paste only the encoded value, without the ApiKey prefix; DBX adds the Authorization: ApiKey … header to every request. Username is not used in this mode. Both direct and Kibana proxy connections use the selected authentication method.
API keys use the existing encrypted password storage and follow Save password (uncheck it for session-only credentials). Existing connections continue to use Basic username/password authentication. Switching authentication methods clears the credential field so you can enter the new credential.
For CLI/MCP configurations, set external_config.authType to "apiKey" and put the encoded key in password; do not put the key in URL parameters or external_config.
Local Test Environments
The repository includes pinned Docker Compose labs for ClickHouse, MariaDB, MongoDB, MySQL, PostgreSQL, and Redis. Use Database Test Lab for connection, driver, and regression testing.